What ComfyUI is, and why VFX artists use it
ComfyUI is a node graph for generative AI models. Every model, setting and file sits in the graph, where you can see it and change it. No step hides behind a button.
It is open source. The same graph runs on your own GPU, on a rented GPU, or on Comfy Cloud, which runs the open-weight models of the official templates.
A result can be repeated. The seed is fixed, the version can be frozen, and every PNG or MP4 that ComfyUI saves carries its graph: drop the file back into ComfyUI and the graph opens. The Comfy team publishes official templates, graphs that work with a model's files. New models often arrive on the day of their release.
Custom nodes add features. MCP, the Model Context Protocol, is a standard way for an AI assistant to drive a tool. An API and MCP connect ComfyUI to a pipeline and to tools such as Nuke, Houdini and Unreal Engine. Through MCP, an AI assistant can also build a first version of a Houdini scene, or the blocking geometry that art-directs a ComfyUI generation.
There is a cost. The start is steeper, and a custom node can break at an update. In production, start from the templates, freeze the version that works, and add custom nodes sparingly. ComfyUI also moves fast: in October and November 2026, a new version landed about every week.
How you steer a model: the four levers
Four levers steer what a model generates.
- The prompt says what the result shows.
- A LoRA is a small file trained on your own images or clips. It adds a style, a character or a motion that the base model lacks.
- A structure pass keeps a layout, edges, volumes or a motion. Canny (an edge detector), Depth Anything 3 (a depth estimator) or a pose feeds a ControlNet for an image: an add-on that makes the model follow the pass. For a video, it feeds an IC-LoRA, a LoRA that reads a reference video beside the prompt.
- A source to rework is an image, a video or a sound you already have. It is encoded, then regenerated with a denoise below 1, which sets how much of it changes. Or an editing model reads it with an instruction.
The same levers apply to image, video and audio models. A mask from SAM 3.1, a segmentation model, limits any of them to one region of a frame or of a shot. Together, they give the artist control over the result. Part 1 of the Masterclass teaches them hands-on.
What it does in production today
Each block names the open models we teach for the job, and links to the article or the tool where we show it.
Look development and key art
Z-Image Turbo makes photoreal people and fast drafts. MOSS-Image covers a style range from photoreal to anime, writes legible text, and places elements with boxes. Both are under Apache 2.0. Our article on the open image models compares them, with their limits.
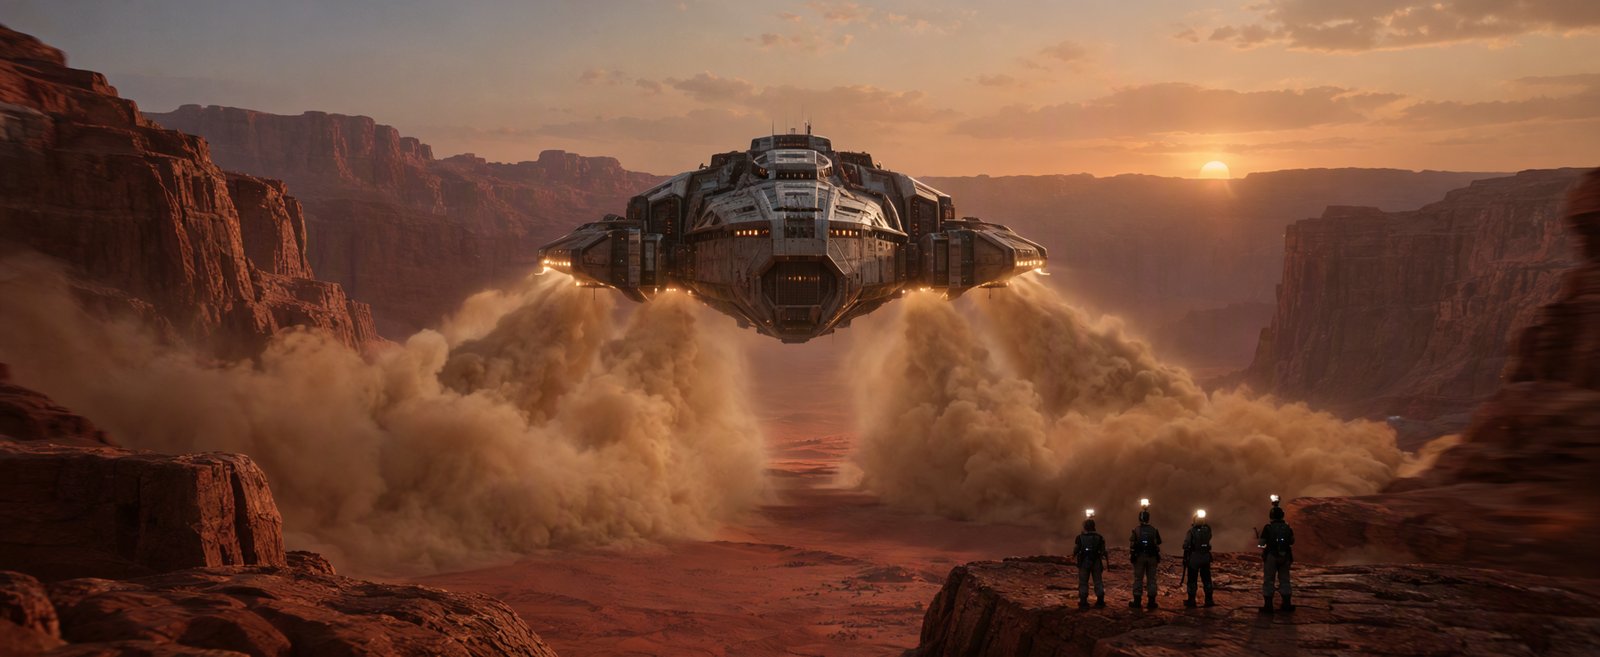
A grey previz blockout becomes a finished frame through a structure pass. Part 2 of the Masterclass ran fourteen production cases, from photoreal people to a delivery at 2K.
Editing a frame, clean plates and relighting
FLUX 3 Image Klein edits a frame by instruction. It takes up to 10 reference images and places objects with boxes. Its weak points are hands, eyes, short prompts and text. Qwen-Image-Edit-2511 stays in our courses for aligned edits and for its LoRAs.
For a whole shot, Paint a plate, our open-source app built on ComfyUI, erases, adds or relights from strokes you paint on the first frame. LTX 2.5 then carries the edit through the shot. It won the Open Weights Only category and the “VFX Workflow Built with LTX” bonus in Comfy's Open Source Higgsfield contest, in November 2026 (the result).
To relight a shot, Klein relights one frame and the Ripple IC-LoRA carries the new light through the shot. Lightricks' Relight IC-LoRA moves the sun on an exterior, and it was not trained on interiors. The showcase of Paint a plate shows a relight, a set extension and a green screen.
A graded frame keeps its look when only the zone is regenerated and composited back. Count the passes through the VAE, the part of the model that turns pixels into its own code and back, and prove with a difference image what did not change.
Storyboards and previz
A participant of our first Bootcamp cohort built a ComfyUI tool that turns a rough sketch into a clean storyboard frame. It keeps the artist's framing, with a LoRA trained for Qwen Image Edit.
Shots from text and from an image
LTX 2.5, from Lightricks, makes video with sound: from text, from an image, or between a first and a last frame. It has 22 billion weights. Part 3 of the Masterclass covers video generation.
Elements: smoke, steam and fire
ainvfx-fluid is our free IC-LoRA for LTX 2.5. Paint flat colour blobs on a first and a last frame, and you get a smoke, steam or fire element about 5 seconds long, in about a minute. We retrained it on an open synthetic dataset that we publish.
Upscaling and restoration
SeedVR2 restores and upscales in one step, with no prompt. We co-developed its ComfyUI node with NumZ before ComfyUI added native support: see the tutorial and version 2.5. It invents texture on an input that is already clean, and it never fixes wrong content: a regeneration does that, or an inpaint, the regeneration of a masked zone.
Masks
SAM 3.1 makes a mask from a word, on a still and across a shot. The mask then limits an edit to its zone, so the rest of the frame keeps its pixels.
3D generation and reconstruction
We teach five routes from images to 3D, all with core ComfyUI nodes. A mesh comes from one image (Pixal3D, TRELLIS.2) or from four views. A Gaussian splat, a cloud of small coloured blobs that shows a captured look from many angles, comes from one image (TripoSplat). A room comes from a 360° panorama (MoGe), and an animated body from a clip (SAM 3D Body). A mesh with PBR maps, the texture maps a physically based renderer reads, takes the lights of your scene. A splat keeps the light it was made with, and relighting a splat is still research.
Participants of our first cohort built Unreal Engine plugins on ComfyUI and a chain that turns one film shot into a set you visit in VR. Part 4 of the Masterclass covers 3D generation.
A LoRA on your own style, character or effect
A LoRA teaches a model what it lacks. A 2-minute short film used LoRAs for Z-Image and LTX 2.3, trained on 73 hand-drawn ink images.
To hold a character from shot to shot, a reference image drives the keyframes, made with Klein or Qwen-Image-Edit, and the keyframes drive the video. A LoRA trained on a small dataset, 25 to 50 images or clips, gives a result of higher quality. ainvfx-runpod trains LoRAs on a rented GPU. Part 5 of the Masterclass covers training.
Colour, EXR and your pipeline
ComfyUI reads float EXR, the image format of VFX pipelines, and keeps values above 1. Save Image (Advanced) writes float EXR, in 16 or 32 bits. The core VAE Decode clamps values between 0 and 1, so what was brighter than white is lost. Paint a plate returns the shot in the plate's own format, and you review it at the plate's quality, an EXR against its EXR, through OpenColorIO as in OpenRV. Part 6 of the Masterclass covers colour, EXR, HDR and the bridges to your tools.
What it does not do yet
- Length and size. LTX 2.5 places every token on a fixed scale of 0 to 20 seconds and 0 to 2,048 pixels per side. A token is one square of 32 x 32 pixels over a packet of 8 frames. Beyond the scale the model still computes, but its quality is no longer guaranteed, and more VRAM (the memory on the graphics card) does not change the scale.
- 4K in two steps. Compose the whole shot within the scale, then enlarge it and refine it in tiles.
- Launch numbers. Lightricks' launch numbers are up to 20 seconds, up to 4K and up to 50 fps. Their documentation gives 32 GB of VRAM as the local minimum. Their guide to running it on your own hardware targets 80 GB or more, and on 32 GB it supports the distilled model, a faster version with fewer steps, with quantized weights: weights stored in a more compact number format. In our courses, LTX 2.5 in int8, one such format, also runs on 16 GB, with part of the model in system RAM, more slowly.
- Cost. The compute follows the tokens: (width ÷ 32) × (height ÷ 32) × ((frames − 1) ÷ 8 + 1). A 5-second shot at 1280 x 704 is 14,080 tokens, and twice the tokens cost about four times the attention compute. On a 16 GB card, one shot of 33 frames at 1920 x 1088 took 1 minute 18 seconds with the distilled model. The full model took about 14 minutes. The price of a shot comes more from the number of tries before the kept take than from one try: draft at low resolution, try several seeds, select, then finish one take.
- Colour depth. Models output 8-bit sRGB, the colour space of screens, in one pass. None delivers the render passes of a 3D render (depth, mattes, IDs): they are estimated afterwards. LTX's SDR to HDR tools write 16-bit EXR in scene-linear light. A generated image still stays SDR (standard dynamic range), because the model learned on images between 0 and 1.
- Exact product fidelity. A generative upscale redesigns a product, so exact fidelity needs a LoRA trained on that product. A Klein edit can also shift the image by a few pixels: pixel-exact alignment needs a frame generated from the source's depth and edges.
- Character consistency comes from reference keyframes or a LoRA, as above.
What you need
- A GPU. 16 GB of VRAM is enough for image work: Z-Image Turbo in int8 runs entirely on the card. For video in production, 32 GB is the realistic minimum. An RTX 5090 (32 GB) gives more resolution and length, and an RTX PRO 6000 (96 GB) is for LoRA training and long or 2K video.
- System RAM and disk. 32 GB of system RAM at minimum, and 64 GB for video and editing, because a large model keeps part of itself in system RAM. Keep 150 GB free on an internal SSD: ComfyUI reloads the models at every change of graph.
- Or a rented GPU. On Runpod, on 15 November 2026, an RTX 5090 rents at 1.39 USD an hour on Secure Cloud, Runpod's own data centres. It rents at 0.69 on Community Cloud, machines owned by third parties. An RTX PRO 6000 rents at 2.69 and 1.69. Prices move: check them when you rent. ainvfx-runpod starts a ready ComfyUI on such a GPU, and our referral link adds free credit when you sign up, in an amount Runpod sets.
Licenses and the law, in short
This section is not legal advice.
- Read two licenses. A model comes in two pieces under two licenses: the code, on GitHub, and the weights, on Hugging Face. Revenue thresholds, excluded territories and forbidden uses live in the license of the weights.
- No threshold. Z-Image Turbo, MOSS-Image, Qwen-Image-Edit-2511, SeedVR2 and Wan 2.2 are under Apache 2.0, which allows commercial use with no revenue threshold. The 3D models we teach (Pixal3D, TRELLIS.2, TripoSplat and MoGe) are under MIT.
- A threshold. The weights of LTX 2.5, and ainvfx-fluid with them, are under the LTX-2.x Community License: a company with annual revenues of 10 million USD or more needs a paid license. The license of FLUX 3 Image Klein allows commercial use of its outputs under 5 million USD of annual revenue, affiliates included.
- Conditions. SAM 3.1 allows commercial use and forbids military and weapons uses. The license of Hunyuan3D excludes the EU, the UK and South Korea, so our courses leave it out.
- Authorship. In the US a copyright needs a human author: on 2 March 2026 the Supreme Court declined to hear Thaler v. Perlmutter. Keep a log per shot (model, version, seed, sources, human edits): it is your chain of rights, and it lets you repeat a frame.
- Marking. Article 50 of the EU AI Act applies since 2 August 2026. Providers mark generated content in a machine-readable way, by 2 December 2026 for systems already on the market, and deployers label deep fakes: content that could pass for real people, objects, places or events.
Our AI ethics page says how we apply this. We label the media we generate. We check where a model's training data comes from before we teach it. We never train on a creator's work without written permission.
How to start
- Install ComfyUI and make a first image. Our installation guide goes from a manual install to a first workflow. A first image on your own machine takes one 4-hour session: Part 1 of the Masterclass.
- Learn one topic at a time with the Masterclass series: six standalone, hands-on parts of 4 hours. Foundations and Image generation are recorded. Video generation, 3D generation, LoRA training and Pipeline integration are live.
- Build a production workflow in the Bootcamp: 60 live, hands-on hours over several weeks, on your own project, with two instructors, two jury reviews and cloud GPUs included. No prior AI experience is needed.
- Train your team on your own shots and pipeline, with studio training.
- Watch for free on our YouTube channel.
Questions
Is ComfyUI used in professional VFX?
The participants of our courses are working professionals who bring a production problem. A 2D supervisor of our first cohort made concept architecture, test shots and a one-minute LTX 2.5 film as his first generative AI projects. Another participant built an image installation that hand gestures drive.
ComfyUI or Nuke?
You keep both. ComfyUI makes and edits pixels with models. Its API and MCP connect it to Nuke, and EXR keeps the plate's range between the two.
Do I need to code?
No. You build a graph of nodes in your browser. The install takes a few commands in a terminal, and on a rented GPU ainvfx-runpod starts from the browser.
Which GPU do I need?
An NVIDIA GPU with 16 GB of VRAM is enough for images. For video in production, plan 32 GB. A rented GPU covers the rest: an RTX 5090 from 0.69 USD an hour on 15 November 2026.
Can I use the result for a client?
Yes, when the license of every model and add-on allows it, and when your contract says how AI is used. Agree on AI use in writing before the job starts. Read the license of the weights before the final pixels, keep a log per shot, and label what the law asks you to label.
How long does it take to learn?
A first image on your own machine takes one 4-hour Masterclass part. A production workflow is what the Bootcamp's 60 hours build, with no prior AI experience needed.